Top 10
Summarize this blog post with:
2026 Verified Rankings · Databricks Consulting
Top 10 Databricks Consulting Companies in the USA (2026)
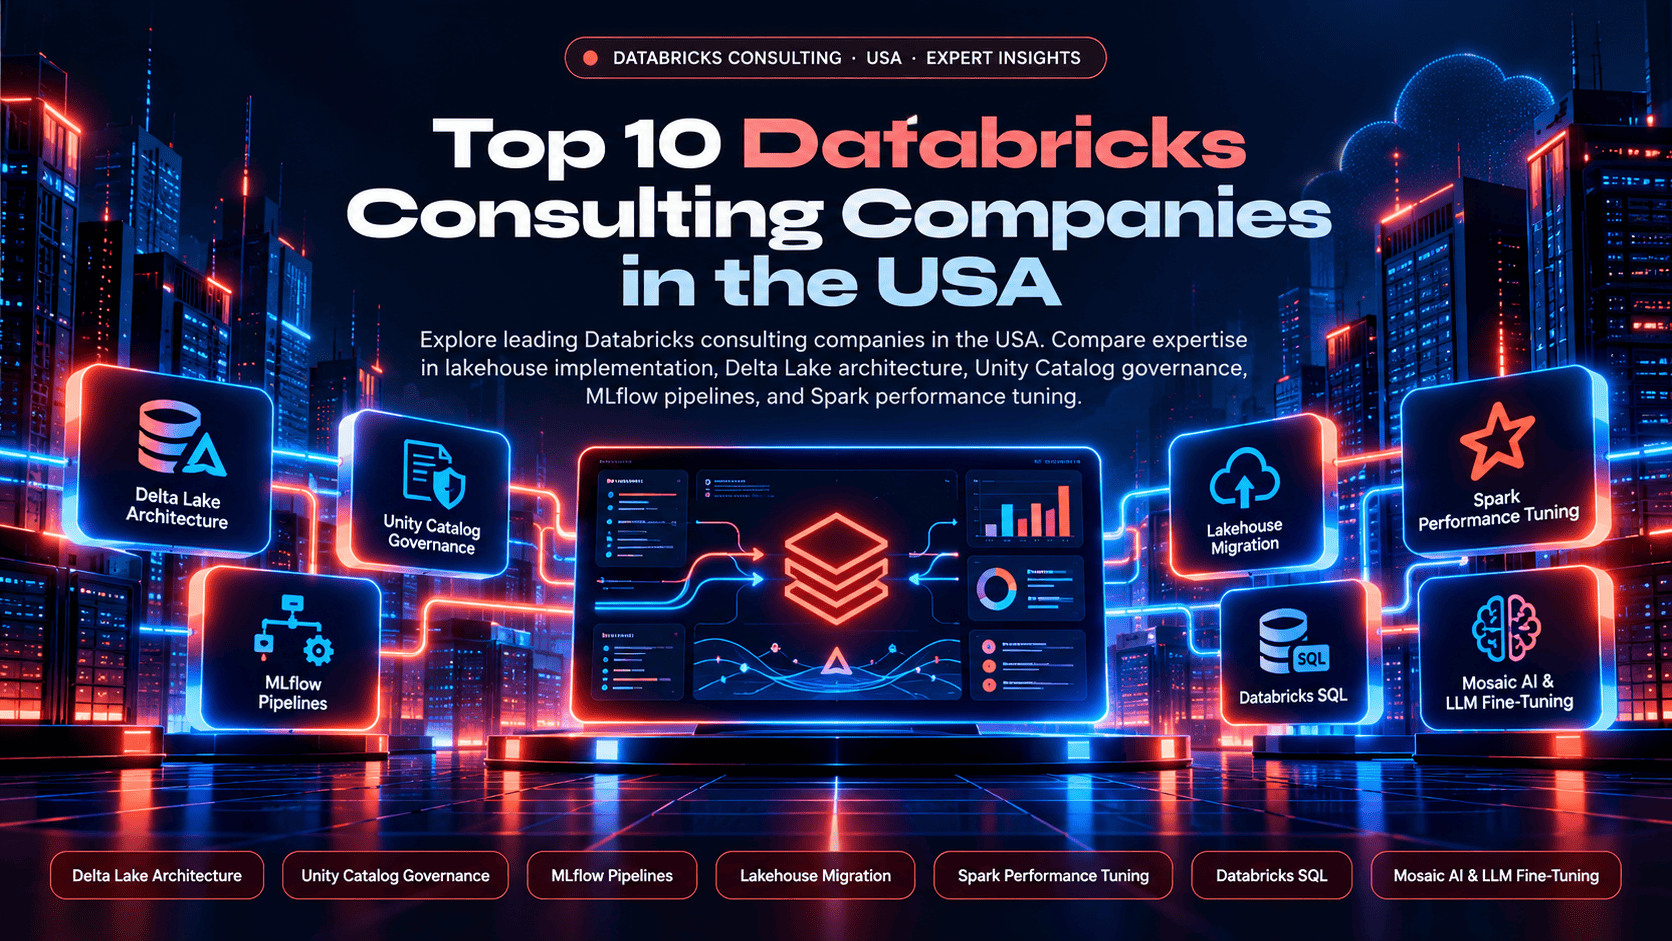
Find the best Databricks consulting companies in the USA for 2026. Compare certified Databricks partners for lakehouse implementation, Delta Lake architecture, Unity Catalog governance, MLflow pipelines, and Spark performance tuning.
Databricks Is the Fastest-Growing Data Company in the World, Here’s Who to Hire
Databricks hit a $5.4 billion revenue run rate with 65% year-over-year growth, driven by explosive adoption of lakehouse architecture and the global demand for unified data and AI platforms. With a $134 billion valuation, Databricks is no longer just a data engineering tool, it’s the infrastructure backbone for organizations building serious AI capabilities, real-time analytics, and governed enterprise data platforms.
But Databricks is powerful precisely because it’s complex. Delta Lake schema evolution and Z-Ordering, Unity Catalog governance design, MLflow experiment tracking at scale, Spark performance tuning, and Mosaic AI model serving all require expertise that takes years to develop in production environments. Wrong configurations lead to runaway compute costs, broken ML pipelines, and datasets that downstream BI tools can’t query efficiently.
We ranked these Databricks consulting partners based on certification tier (Elite and Premier partner status), depth of Delta Lake and Unity Catalog production experience, ML and AI platform delivery capability including MLflow and Mosaic AI, Spark performance engineering track record, Databricks SQL analytics layer quality, and verified client satisfaction on Clutch and G2.
How We Ranked These 10 Databricks Consulting Companies
Sources: Databricks FY2025 Report, IDC Lakehouse Forecast, Forbes 2025. Ranked by: Clutch score · Review count · USA market expertise.
How We Ranked These 10 Databricks Consulting Companies
✓Delta Lake Architecture
✓Unity Catalog Governance
✓MLflow Pipelines
✓Lakehouse Migration
✓Spark Performance Tuning
✓Databricks SQL
✓Mosaic AI and LLM Fine-Tuning
The Top 10 Databricks Consulting Companies in the USA (2026)
#1
Accenture
Clutch Top
4.8Clutch Rating
$150-$300/hrHourly Rate
1,200+ ReviewsClutch Reviews
About Accenture
Accenture is a Databricks Elite partner with dedicated Data Intelligence Platform practices across North America, consistently recognized by Databricks for delivery excellence and enterprise customer outcomes. Their Databricks plus Azure integration blueprints are used by Fortune 100 companies migrating from legacy Hadoop, Spark-on-YARN, and Azure HDInsight environments to Databricks Unity Catalog-governed lakehouses, covering full-cluster migration, Delta Lake format conversion, and Azure Data Factory-to-Databricks Workflows re-platforming. Enterprise lakehouse strategy at Accenture means designing Databricks environments that align with business domain boundaries, data product ownership models, and organizational data mesh principles, not just technical deployment.
Their ML platform on Databricks implementations build production-grade machine learning infrastructure: feature stores using Databricks Feature Engineering, model training at scale using distributed Spark ML and PyTorch, MLflow model registry with automated deployment pipelines, and Model Serving endpoints with traffic management. Unity Catalog enterprise governance at Accenture scale includes cross-workspace metastore federation, automated data classification, policy-as-code governance frameworks, and integration with enterprise identity providers and data catalog tools like Alation and Collibra. Their regulatory compliance on Databricks practice is particularly mature for financial services clients that need Databricks environments certified for BCBS 239, CCAR, and model risk management frameworks. Best for Fortune 500 organizations with complex existing Azure or multi-cloud data ecosystems, significant Hadoop or HDInsight technical debt, and the budget to invest in enterprise-grade Databricks architecture and governance.
Core Services
💡 Best for: Enterprise
📍 New York, NY · Global Delivery
#2
Tiger Analytics
Clutch Verified
4.8Clutch Rating
$75-$140/hrHourly Rate
160+ ReviewsClutch Reviews
About Tiger Analytics
Tiger Analytics builds AI-first lakehouses on Databricks, designing unified environments where data engineering pipelines, feature engineering workflows, model training infrastructure, and production inference serving all coexist within a single governed platform. Their feature store implementations on Databricks are a key differentiator for companies building recommendation systems, personalization engines, real-time fraud detection, and demand forecasting models that need consistent, point-in-time correct features across training and serving. Real-time ML pipeline engineering at Tiger Analytics covers Databricks Structured Streaming for continuous feature computation, Delta Live Tables for streaming data quality management, and Mosaic AI Model Serving for low-latency inference with automatic scaling.
Their lakehouse architecture design practice is grounded in practical AI delivery, designing Delta Lake schemas, partition strategies, and Z-Order configurations that optimize for the feature retrieval patterns that ML models actually need. MLflow experiment management at scale is a Tiger Analytics specialty, building experiment tracking systems where data scientists log hundreds of training runs, compare hyperparameter configurations, and promote champion models through staging workflows to production deployment, all with full reproducibility and lineage tracking. Their AI model operationalization practice covers the full MLOps lifecycle from model registration through A/B testing, shadow deployment, and production monitoring with drift detection. Strong in CPG, retail, financial services, and telecommunications verticals where ML-at-scale is a revenue-critical capability, not an experimental initiative.
Core Services
💡 Best for: AI-first organizations
📍 San Jose, CA · US Delivery
#3
Tredence
Clutch Top
4.9Clutch Rating
$80-$160/hrHourly Rate
210+ ReviewsClutch Reviews
About Tredence
Tredence has made Databricks the centerpiece of their data and AI delivery practice, with specialized lakehouse analytics teams built around CPG, retail, manufacturing, and supply chain industry verticals that demand both high-volume data processing and production ML at scale. Their Unity Catalog governance frameworks are engineered for enterprise-grade data access controls, designing hierarchical privilege structures, attribute-based access policies, column masking for PII, and comprehensive audit logging that gives compliance teams the data lineage visibility they require. Supply chain AI on Databricks is a Tredence flagship, building demand forecasting models, inventory optimization engines, supplier risk scoring systems, and logistics routing ML models that run on Delta Lake-backed feature stores and deploy through MLflow-managed serving infrastructure.
Their Databricks SQL BI layer implementations design analytical views, materialized aggregations, and Databricks SQL warehouses that expose lakehouse data to Tableau, Power BI, and Looker users without requiring Spark expertise. Delta Live Tables pipeline engineering at Tredence brings declarative data quality constraints, automatic dependency resolution, and incremental processing management to complex multi-source data ingestion workflows, simplifying pipeline development and dramatically reducing the operational burden of maintaining production Databricks pipelines. Their CPG and retail lakehouse implementations consolidate POS transaction data, e-commerce clickstream, third-party syndicated data, and CRM sources into governed, ML-ready Delta Lake environments. A top choice for CPG, manufacturing, and retail organizations that need Databricks expertise grounded in deep industry data and AI knowledge.
Core Services
💡 Best for: CPG and Manufacturing
📍 San Jose, CA · US Headquarters
#4
phData
Clutch Top
4.9Clutch Rating
$100-$180/hrHourly Rate
200+ ReviewsClutch Reviews
About phData
phData’s Databricks practice is consistently rated among the best in the country for clean, well-architected lakehouse builds, a Databricks Premier partner with a team of senior engineers who bring analytics engineering discipline to every Delta Lake implementation. Their dbt-on-Databricks methodology brings the same version control, testing, documentation, and lineage rigor that made dbt a modern data stack standard to the Delta Lake environment, ensuring transformation logic is modular, peer-reviewed, and business-team maintainable long after the engagement ends. Delta Lake optimization at phData goes deep into platform internals: Z-Order clustering key selection based on query filter cardinality analysis, file size tuning for micro-partition efficiency, OPTIMIZE and VACUUM scheduling, liquid clustering evaluation for evolving query patterns, and predictive I/O configuration for accelerated reads.
Their engineers understand why Spark’s adaptive query execution makes certain join strategies faster and how to configure Databricks to take full advantage. Databricks plus Snowflake architecture strategy is a phData specialty, advising clients on where to draw the boundary between lakehouse processing in Databricks and governed analytics in Snowflake, designing Delta Sharing and zero-copy patterns that let both platforms access the same physical data without duplication, and building unified governance that spans both environments. Their MLflow engineering practice covers tracking, model registry, deployment pipelines, and integration with Databricks Feature Engineering for reproducible ML workflows. Best for analytics-first organizations that want Databricks implemented with engineering rigor, proper documentation, and long-term maintainability as primary design principles.
Core Services
💡 Best for: Analytics-first orgs
📍 Minneapolis, MN · US Headquarters
#5
Deloitte
Clutch Verified
4.7Clutch Rating
$200-$400/hrHourly Rate
800+ ReviewsClutch Reviews
About Deloitte
Deloitte deploys Databricks for enterprise digital transformation programs where governance, auditability, change management, and AI risk management are as critically important as technical delivery quality. Their AI governance frameworks on Databricks are trusted by financial institutions and healthcare systems that need model explainability, audit trails for ML decisions, model validation workflows, and regulatory documentation for every production model, meeting SR 11-7 model risk management requirements for bank-supervised AI systems. Enterprise lakehouse program management at Deloitte means running Databricks implementations as structured transformation programs with executive sponsorship, formal steering committee governance, risk management frameworks, and workforce change management programs that ensure data engineering teams, data scientists, and business users all develop the Databricks fluency the platform requires.
Their Databricks governance and risk practice designs Unity Catalog environments that satisfy internal audit, regulatory examination, and third-party risk management requirements. Regulated industry Databricks deployments at Deloitte cover financial services, healthcare, life sciences, and government, where data residency requirements, encryption key management, private networking, and access certification programs add significant complexity to Databricks environment design. Their AI risk management on Databricks practice includes model inventory management, challenger model testing frameworks, and automated model monitoring with statistical drift detection. Best for highly regulated enterprises where governance, compliance, and organizational change management dimensions of a Databricks implementation matter as much as the technical architecture and data engineering quality.
Core Services
💡 Best for: Regulated industries
📍 New York, NY · National USA
#6
Slalom
Clutch Top
4.9Clutch Rating
$120-$220/hrHourly Rate
350+ ReviewsClutch Reviews
About Slalom
Slalom was an early adopter of Databricks’ Data Intelligence Platform positioning, building AI-native lakehouses for clients across financial services, healthcare, and technology sectors that go beyond traditional data engineering to embed AI capabilities directly into the data platform infrastructure. Their Genie and Databricks AI Gateway implementations help business teams interact with lakehouse data using natural language queries, building the conversational analytics layer on top of governed Delta Lake tables so non-technical stakeholders can self-serve insights without SQL expertise. Lakehouse architecture design at Slalom is grounded in a data mesh and data product philosophy, defining domain ownership, designing data contracts between producer and consumer domains, and building the self-serve infrastructure that lets business domains publish and consume data products independently within the Databricks Unity Catalog governance framework.
Their Delta Sharing architecture implementations enable secure, governed data exchange between internal business units and external partners without data duplication. Databricks plus Azure integration is a Slalom strength, connecting Azure Data Factory orchestration, Azure Event Hubs streaming ingestion, Azure Machine Learning model management, and Azure Active Directory identity governance with Databricks workspace environments. Their analytics engineering on Databricks practice uses dbt-core with the Databricks adapter to bring SQL-first transformation discipline to Delta Lake pipelines. Particularly strong for organizations adopting Databricks as a company-wide Data Intelligence Platform rather than a point solution for specific data engineering teams.
Core Services
💡 Best for: Enterprise
📍 Seattle, WA · US Headquarters
#7
Innowise
Clutch Verified
4.8Clutch Rating
$50-$100/hrHourly Rate
110+ ReviewsClutch Reviews
About Innowise
Innowise brings deep Apache Spark and distributed computing expertise to Databricks engagements, specializing in performance-critical pipeline engineering where compute cost, job SLAs, and cluster efficiency are the primary delivery metrics. Their Spark performance tuning engagements have consistently reduced Databricks cluster costs by 40-60% for clients with poorly optimized existing deployments, through systematic diagnosis of shuffle overhead, partition skew, broadcast threshold misconfigurations, driver memory pressure, and inefficient file format choices that cause unnecessary I/O. Databricks cluster configuration optimization covers autoscaling policy design, instance type selection for different workload profiles (memory-optimized for joins and aggregations, compute-optimized for CPU-intensive transformations), Photon engine configuration for SQL-heavy workloads, and spot instance strategies that reduce Databricks compute costs without compromising job reliability.
Their Delta Lake schema and partition design practice focuses on the physical layout decisions that determine long-term query performance: partition column cardinality, partition pruning effectiveness, file size targeting, and Z-Order column selection. ETL-to-Databricks migration at Innowise covers re-platforming from Informatica, Talend, SSIS, and Pentaho environments to Databricks Workflows and Delta Live Tables, converting proprietary transformation logic to PySpark, Scala Spark, or SQL notebooks with proper dependency management and error handling. Their custom Databricks integrations include REST API-based automation, Databricks CLI scripting, DBFS management, and Databricks partner connect integrations. The right choice for engineering-driven organizations where Spark performance and compute cost efficiency are the primary Databricks project success criteria.
Core Services
💡 Best for: Cost-optimization focus
📍 New York, NY · US Delivery
#8
DataForest
Clutch Verified
4.8Clutch Rating
$60-$110/hrHourly Rate
85+ ReviewsClutch Reviews
About DataForest
DataForest specializes in building production AI applications directly on Databricks, using Mosaic AI, Vector Search, LLM fine-tuning capabilities, and MLflow’s model lifecycle management to create enterprise AI systems that live within the governed lakehouse environment rather than in isolated external AI platforms. Their OpenAI-on-Databricks integration pattern has become a standard architecture for enterprise AI teams that need to combine OpenAI’s foundation models with internal, governed enterprise data stored in Delta Lake, without copying sensitive data outside the Databricks security perimeter. LLM fine-tuning on Databricks at DataForest covers instruction tuning of open-source foundation models (Llama, Mistral, Mixtral) on domain-specific enterprise data using Databricks’ distributed training infrastructure, enabling clients to build specialized models for document processing, code generation, customer service automation, and knowledge retrieval that outperform general-purpose models on industry-specific tasks.
Their Mosaic AI Vector Search implementations build semantic retrieval infrastructure directly within Databricks, supporting RAG architectures where enterprise documents, support tickets, and knowledge base articles are embedded, indexed, and retrieved in response to natural language queries. RAG system architecture at DataForest designs end-to-end retrieval-augmented generation pipelines: document ingestion, chunking, embedding generation, vector index management, retrieval with reranking, and generation with source attribution, all governed through Unity Catalog and monitored through MLflow. Their Databricks Model Serving deployments configure auto-scaling inference endpoints with latency SLAs, A/B testing, and integrated request logging for model performance monitoring. The specialist choice for product and data teams building AI-powered applications, enterprise search systems, or LLM-based automation directly on their Databricks lakehouse.
Core Services
💡 Best for: AI product teams
📍 Austin, TX · US Operations
#9
Lovelytics
Clutch Top
4.9Clutch Rating
$80-$150/hrHourly Rate
75+ ReviewsClutch Reviews
About Lovelytics
Lovelytics bridges the gap between Databricks engineering teams and business analytics consumers, a specialized BI consulting firm that builds the Databricks SQL layer, semantic models, and BI tool integrations that transform raw lakehouse data into actionable insights for non-technical stakeholders in operations, finance, marketing, and executive leadership. Their self-service analytics frameworks on Databricks drive adoption far beyond data engineering teams, enabling business users to query lakehouse data through Power BI, Tableau, or Databricks Genie without understanding Spark, Delta Lake, or distributed computing concepts. Databricks SQL analytics layer design at Lovelytics covers SQL warehouse sizing and configuration for concurrent BI query performance, view and materialized view design that optimizes frequently run dashboard queries, column-level statistics maintenance, and query result caching strategies that dramatically reduce credit consumption for repeated dashboard refreshes.
Their Power BI on Databricks implementations include DirectQuery mode configuration with query folding optimization, Import mode lakehouse snapshots for maximum dashboard performance, and row-level security synchronized between Databricks Unity Catalog and Power BI data model roles. Tableau on Databricks lakehouse integration at Lovelytics covers Spark SQL connector configuration, Hyper extract optimization for large Delta Lake tables, and Tableau Published Data Source design that gives analysts governed, pre-certified data connections without needing Databricks workspace access. Their dashboard and report migration practice moves existing Business Objects, SSRS, Cognos, and legacy BI tool reports to Databricks SQL-backed Power BI or Tableau equivalents. The go-to Databricks partner when the primary challenge is making lakehouse data accessible and actionable for business users, not building the engineering infrastructure.
Core Services
💡 Best for: BI-focused teams
📍 Arlington, VA · US Headquarters
#10
Perficient
Elite status announced March 2025
Not listedClutch Rating
Not publishedHourly Rate
120+Databricks-Certified Consultants
About Perficient
Perficient, based in St. Louis, announced Databricks Elite Partner status on March 17, 2025, citing its data and AI expertise and its success with the Databricks Data Intelligence Platform.
It says it has more than 120 Databricks-certified consultants covering data engineering, data warehousing, AI and ML, data science, and data governance. Perficient is a large digital consultancy, so engagements tend toward enterprise scale. Pricing is not published and no Clutch rating is listed here, so request references and a scoped discovery before committing.
Core Services
💡 Best for: Enterprises that want a large Databricks Elite partner with broad delivery capacity.
📍 St. Louis, MO · Large digital consultancy
Quick Comparison: Top 10 Companies
All rankings based on Clutch verified reviews, September 2026. Entry 10 is based on the firm’s own published information and its Clutch listing where available.
| # | Company | Rating | Status | Rate | Best For | Why Choose |
|---|---|---|---|---|---|---|
| 1 | Accenture | ★★★★☆ 4.8 | Elite Partner | $150-$300/hr | Enterprise | Azure + Databricks, large-scale migrations, governance |
| 2 | Tiger Analytics | ★★★★☆ 4.8 | Clutch Verified | $75-$140/hr | AI-first organizations | Feature stores, real-time ML pipelines, MLOps |
| 3 | Tredence | ★★★★★ 4.9 | Clutch Top | $80-$160/hr | CPG and Manufacturing | Unity Catalog, supply chain AI, Delta Live Tables |
| 4 | phData | ★★★★★ 4.9 | Premier Partner | $100-$180/hr | Analytics-first orgs | dbt on Databricks, Delta Lake optimization, dual-platform strategy |
| 5 | Deloitte | ★★★★☆ 4.7 | Big 4 | $200-$400/hr | Regulated industries | AI governance, model risk management, compliance |
| 6 | Slalom | ★★★★★ 4.9 | Clutch Top | $120-$220/hr | Enterprise | Data Intelligence Platform, Genie AI, data mesh |
| 7 | Innowise | ★★★★☆ 4.8 | Clutch Verified | $50-$100/hr | Cost-optimization focus | Spark tuning, cluster optimization, 40-60% cost reduction |
| 8 | DataForest | ★★★★☆ 4.8 | Clutch Verified | $60-$110/hr | AI product teams | LLM fine-tuning, Mosaic AI, RAG systems, Vector Search |
| 9 | Lovelytics | ★★★★★ 4.9 | Clutch Top | $80-$150/hr | BI-focused teams | Databricks SQL, Power BI and Tableau on lakehouse |
| 10 | Perficient | Not listed | Databricks Elite (2025) | Not published | Enterprise programs | Databricks Elite partner with 120+ certified consultants across data and AI |
Frequently Asked Questions
Common questions about top 10 databricks consulting companies in the USA.
Who are the best Databricks consulting companies in the USA?
Based on this ranking, the best Databricks consulting companies in the USA are Accenture, Tiger Analytics, and Tredence. The comparison table above lists each firm’s rating, rate, and best-fit use case, so you can match one to your project and budget.
What does a Databricks consulting company do?
Databricks consulting companies design, implement, and optimize lakehouse data platforms on the Databricks Data Intelligence Platform. Core services include Delta Lake architecture design with schema enforcement, ACID transactions, and Z-Order optimization; Unity Catalog governance setup with role-based access controls, data lineage tracking, and column-level masking; MLflow pipeline engineering for end-to-end ML lifecycle management; Spark performance tuning and compute cost optimization; Databricks SQL analytics layer design for BI tool integration; Mosaic AI and LLM implementation for enterprise AI applications; and migrating from legacy Hadoop, Spark-on-YARN, Azure HDInsight, and cloud data warehouse environments to governed Databricks lakehouses. Experienced Databricks consultants also design streaming architectures using Structured Streaming and Delta Live Tables for real-time data processing.
How much does Databricks consulting cost in the USA?
Databricks consulting rates in the USA typically range from $50 to $400 per hour depending on firm type, specialization, and engagement scope. Boutique Databricks specialists and AI-focused firms charge $60-$140/hr for Spark engineering, ML pipeline development, and lakehouse implementation. Mid-tier analytics engineering firms with Databricks Premier certification range from $80-$180/hr. Large enterprise systems integrators like Accenture and Deloitte charge $150-$400/hr for strategic governance, enterprise migration programs, and regulated industry implementations. Spark performance tuning engagements often deliver immediate ROI, reducing Databricks compute costs by 40-60% in environments with poorly optimized existing workloads, frequently paying for the consulting engagement through credit savings alone.
What is the difference between Databricks and Snowflake?
Databricks is a unified lakehouse platform built on Apache Spark, designed for data engineering, ML and AI workloads, unstructured data processing, and streaming analytics using Python, Scala, SQL, and R. Snowflake is a cloud data warehouse optimized for structured data, SQL analytics, governed BI reporting, and multi-organization data sharing. Many enterprises deploy both in complementary architectures: Databricks handles raw data ingestion, feature engineering, ML model training, and complex transformation logic; Snowflake serves as the governed, SQL-optimized analytics layer for business reporting teams using Tableau, Power BI, or Looker. Databricks has a significant edge for ML-heavy workloads, unstructured data, and AI application development. Snowflake excels for concurrent BI queries, data sharing between organizations, and SQL-centric analytics teams.
What is Unity Catalog in Databricks?
Unity Catalog is Databricks’ unified governance layer, a centralized metastore that manages data access controls, column-level security, row-level filtering, data lineage tracking, and comprehensive audit logging across all Databricks workspaces in an organization. Before Unity Catalog, Databricks environments used workspace-level Hive metastores that created governance fragmentation across multi-workspace deployments, making enterprise-scale data governance extremely difficult to manage. Unity Catalog solves this by providing a single governance control plane where administrators define hierarchical privilege structures (catalog, schema, table, column), automated data lineage graphs that show exactly where data came from and where it flows, and fine-grained access policies that can satisfy HIPAA, SOX, GDPR, and CCPA requirements. It is now the governance foundation required for enterprise Databricks deployments.
How do I choose the right Databricks consulting partner?
Start by verifying Databricks certification tier, Elite and Premier partners have demonstrated certified engineering depth and verified production delivery track records that individual Databricks experience cannot match. Ask specifically about Unity Catalog governance experience, Delta Lake production implementations including schema evolution and Z-Order management, and MLflow model lifecycle management, not just general Spark or Python usage. Request case studies showing lakehouse migrations from legacy environments with specific compute cost outcomes. Evaluate Spark performance tuning capability, because cost optimization is often immediate ROI in existing Databricks deployments. Check client reviews on Clutch and G2 for delivery quality signals. For AI-heavy workloads, ask about Mosaic AI, LLM fine-tuning, and Vector Search experience. Finally, evaluate cultural fit, Databricks implementations are often 6-18 month engagements where team communication and knowledge transfer matter as much as technical expertise.
Bottom Line: Which USA Company Is Right for You?
Databricks is no longer a niche data science tool, it is the AI infrastructure layer for serious data-driven enterprises building production ML systems, real-time analytics platforms, and AI-powered applications on governed, scalable lakehouses. Getting your lakehouse architecture right, Unity Catalog governance in place, and Spark performance optimized from day one determines whether your AI investments build compound value or accumulate expensive technical debt.
When comparing Databricks partners, confirm tier status in Databricks’ partner directory, ask for a reference on a comparable Unity Catalog and Delta Lake rollout, and agree on how cluster costs and job reliability will be monitored. Large integrators suit multi-year platform programs, while focused specialists often get a first lakehouse workload live sooner.
Related reading: Top 10 Data Analytics Companies in the USA · Top 10 Microsoft Fabric Consulting Companies in the USA · Top AI and ML Development Companies in the USA · Top DevOps Consulting Companies in the USA
Schedule a call
Talk to a subject-matter expert
Web development, SEO, or digital marketing — tell us about your project and we'll get back within one business day. No obligation.
- Free scope & strategy session
- A senior specialist, not a sales rep
- Your details stay confidential